◀ IA · 31 OUT14/15
Lançamento
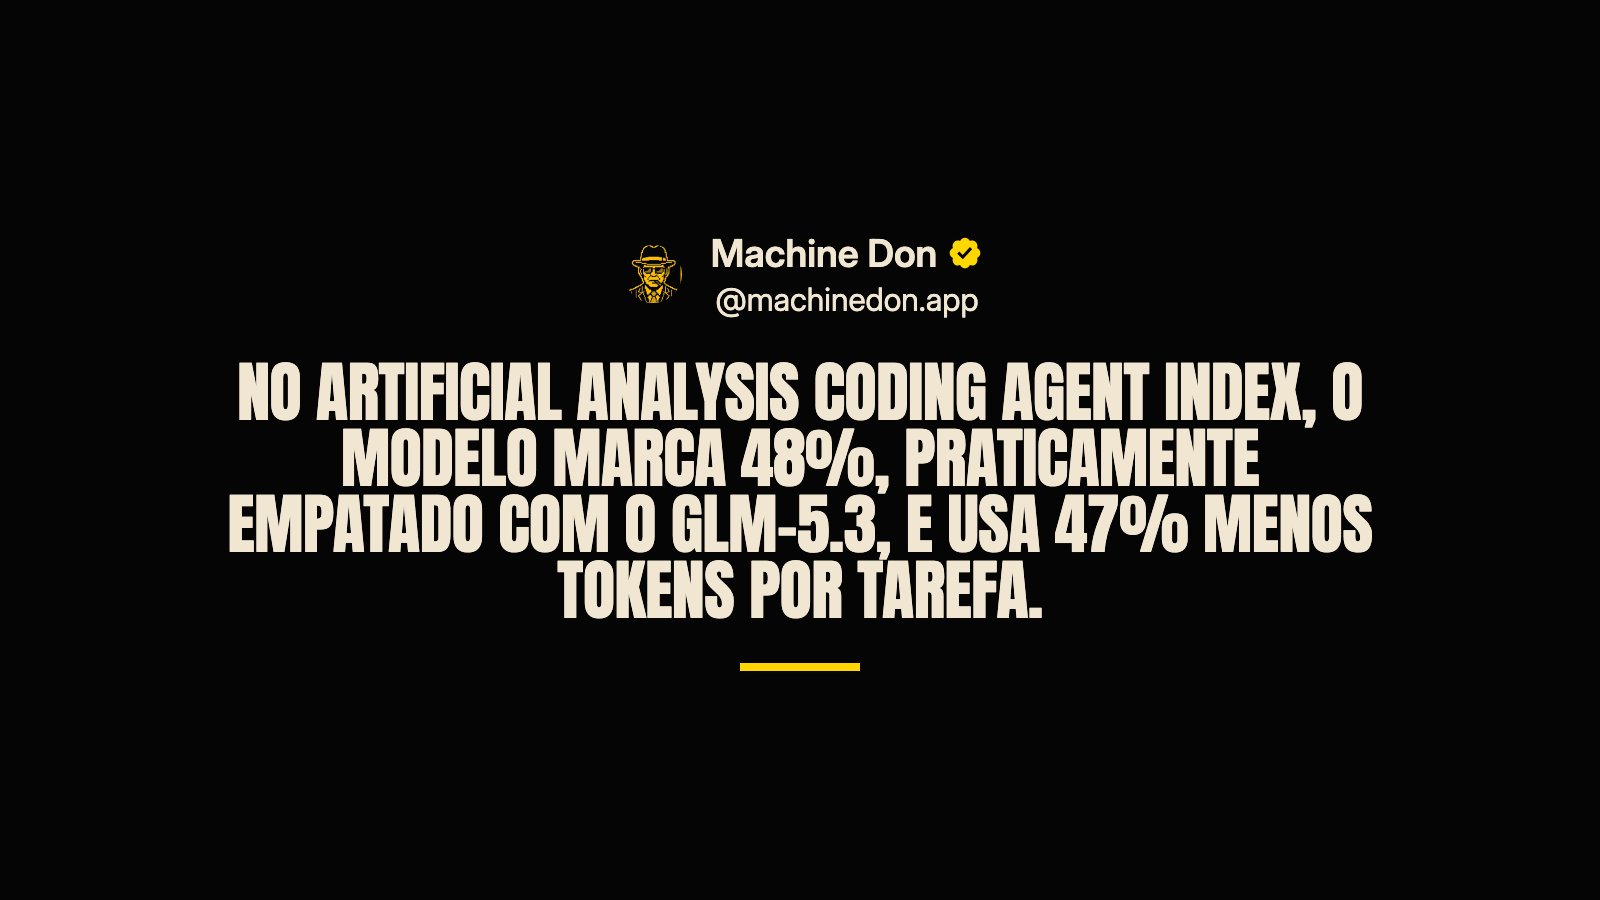
No Artificial Analysis Coding Agent Index, o modelo marca 48%, praticamente empatado com o GLM-5.3, e usa 47% menos tokens por tarefa.
No Artificial Analysis Coding Agent Index, o modelo marca 48%, praticamente empatado com o GLM-5.3, e usa 47% menos tokens por tarefa.
Mistral Large 4 scores 48%, effectively tied with the leading open-weight model, GLM-5.3, while using 47% fewer tokens per task on average
mistral.ai
Segundo a Mistral, é o melhor modelo open-weight para programação.
Mistral Large 4 ranks as the best open-weight model for coding
mistral.ai
No Artificial Analysis Cyber Index, o modelo marca 51%.
Mistral Large 4 scores 51% on the Artificial Analysis Cyber Index
mistral.ai